Mahalanobis Distance
Mahmood Amintoosi, Fall 2026
Computer Science Dept, Ferdowsi University of Mashhad
The covariance material follows chapter 2 of Pattern Classification by Duda, Hart, and Stork (Duda et al. (2000)), whose notation we use; the geometric explanations are adapted from Vision Dummy and from the SAS blog on the Mahalanobis distance.
Learning objectives. By the end you should be able to
say why Euclidean distance fails when features have different units or are correlated;
read a covariance matrix, and its eigenvalues and eigenvectors, as shape and orientation;
prove that ;
build the whitening matrix and show that whitening turns the Mahalanobis distance into a Euclidean one;
compute Mahalanobis distances and whitened coordinates with NumPy;
tell apart standardization, PCA and whitening;
place the Mahalanobis distance in the Gaussian discriminant of Bayesian decision theory.
1. Why Do We Need the Mahalanobis Distance?
In most applications the data are multivariate, the features are correlated and they are measured on different scales. The Euclidean distance () assumes the opposite: uncorrelated features with the same variance. If one feature is in metres and another in kilometres, the second one dominates the sum by its numerical size alone. If the features are correlated, the cloud is an ellipsoid rather than a sphere, and Euclidean distance ignores the orientation of that ellipsoid — misleading results in classification and in clustering follow.
The Mahalanobis distance measures the distance between a point and a distribution, normalised by the variance of each feature and by the correlations between them.
Illustrative Example: Euclidean versus Mahalanobis
A two-dimensional Gaussian with high correlation, and two points at the same Euclidean distance from its centre, one along the direction of large variance and one across it:
Source
import numpy as np
import matplotlib.pyplot as plt
from scipy.spatial.distance import mahalanobis
from scipy.stats import multivariate_normal

# Set random seed for reproducibility
np.random.seed(42)

# Generate 2D Gaussian random points with high correlation
mean = [0, 0]
cov = [[1, 0.8], [0.8, 1]]  # Covariance matrix
points = np.random.multivariate_normal(mean, cov, 100)

# Select two points with the same Euclidean distance to the center but different locations
# Point 1 is along the direction of high variance
# Point 2 is along the direction of low variance
point1 = np.array([1.5, 1.5])
point2 = np.array([-1.5, 1.5])

# Compute Euclidean distances
center = np.array(mean)
euclidean_dist1 = np.linalg.norm(point1 - center)
euclidean_dist2 = np.linalg.norm(point2 - center)

# Compute Mahalanobis distances
inv_cov = np.linalg.inv(cov)
mahalanobis_dist1 = mahalanobis(point1, center, inv_cov)
mahalanobis_dist2 = mahalanobis(point2, center, inv_cov)

# Plot the data and points
plt.figure(figsize=(10, 8))
plt.scatter(points[:, 0], points[:, 1], alpha=0.5, label='Data Points')
plt.scatter(center[0], center[1], color='red', marker='x', s=100, label='Mean (0,0)')

# Highlight the two comparison points
plt.scatter(point1[0], point1[1], color='green', marker='*', s=150,
            label=f'Point 1\nEuclidean: {euclidean_dist1:.2f}, Mahal: {mahalanobis_dist1:.2f}')
plt.scatter(point2[0], point2[1], color='blue', marker='*', s=150,
            label=f'Point 2\nEuclidean: {euclidean_dist2:.2f}, Mahal: {mahalanobis_dist2:.2f}')

# Plot the probability contours
x, y = np.mgrid[-3:3:.01, -3:3:.01]
pos = np.dstack((x, y))
rv = multivariate_normal(mean, cov)
plt.contour(x, y, rv.pdf(pos), levels=3, colors='purple', linewidths=2)

plt.legend()
plt.title('Euclidean vs. Mahalanobis Distance')
plt.xlabel('Feature 1')
plt.ylabel('Feature 2')
plt.grid(True, linestyle='--', alpha=0.3)
plt.axis('equal')
plt.tight_layout()
plt.show()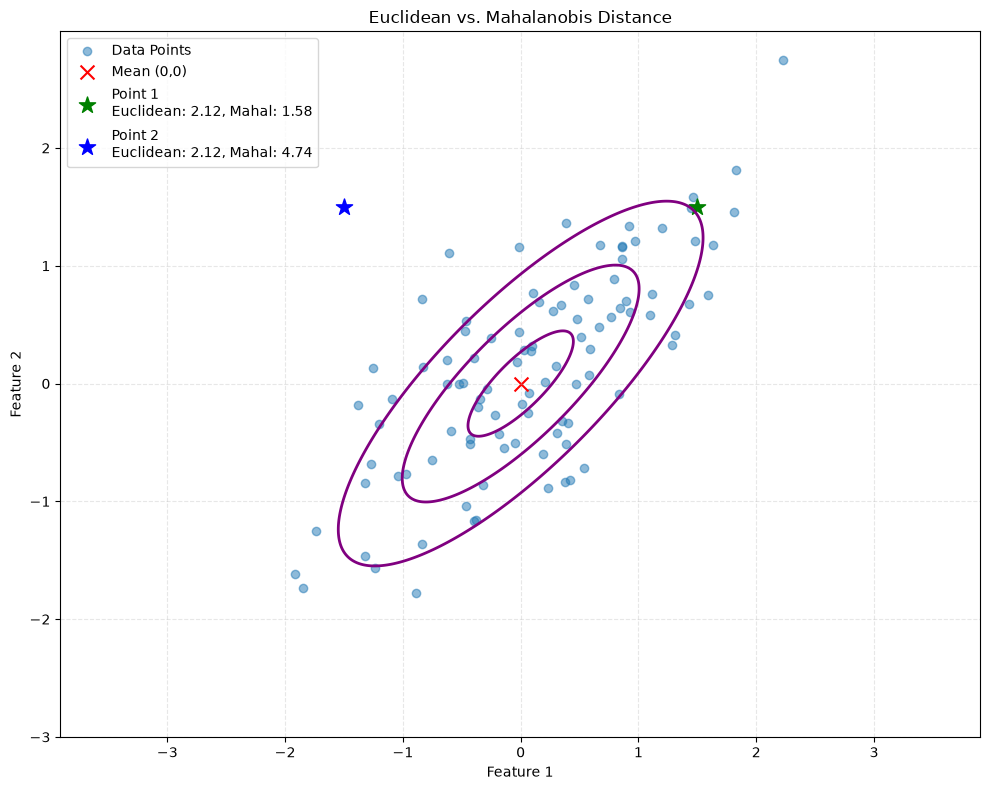
Observation: Point 1 and Point 2 have the same Euclidean distance from the center, yet they lie in different “probability regions.” Point 2 is in a direction of lower variance (orthogonal to the main correlation), making it statistically less likely (further in Mahalanobis distance) than Point 1.
2. Feature Scaling: A Case Study
The Data
Three ballistic missiles, described by two features: range and speed.
| Missile | Range (km) | Speed (Mach) |
|---|---|---|
| A. Khaybar Shikan (target) | 1,450 | 5 |
| B. Sejjil | 2,000 | 10 |
| C. Fatāh | 1,400 | 14 |
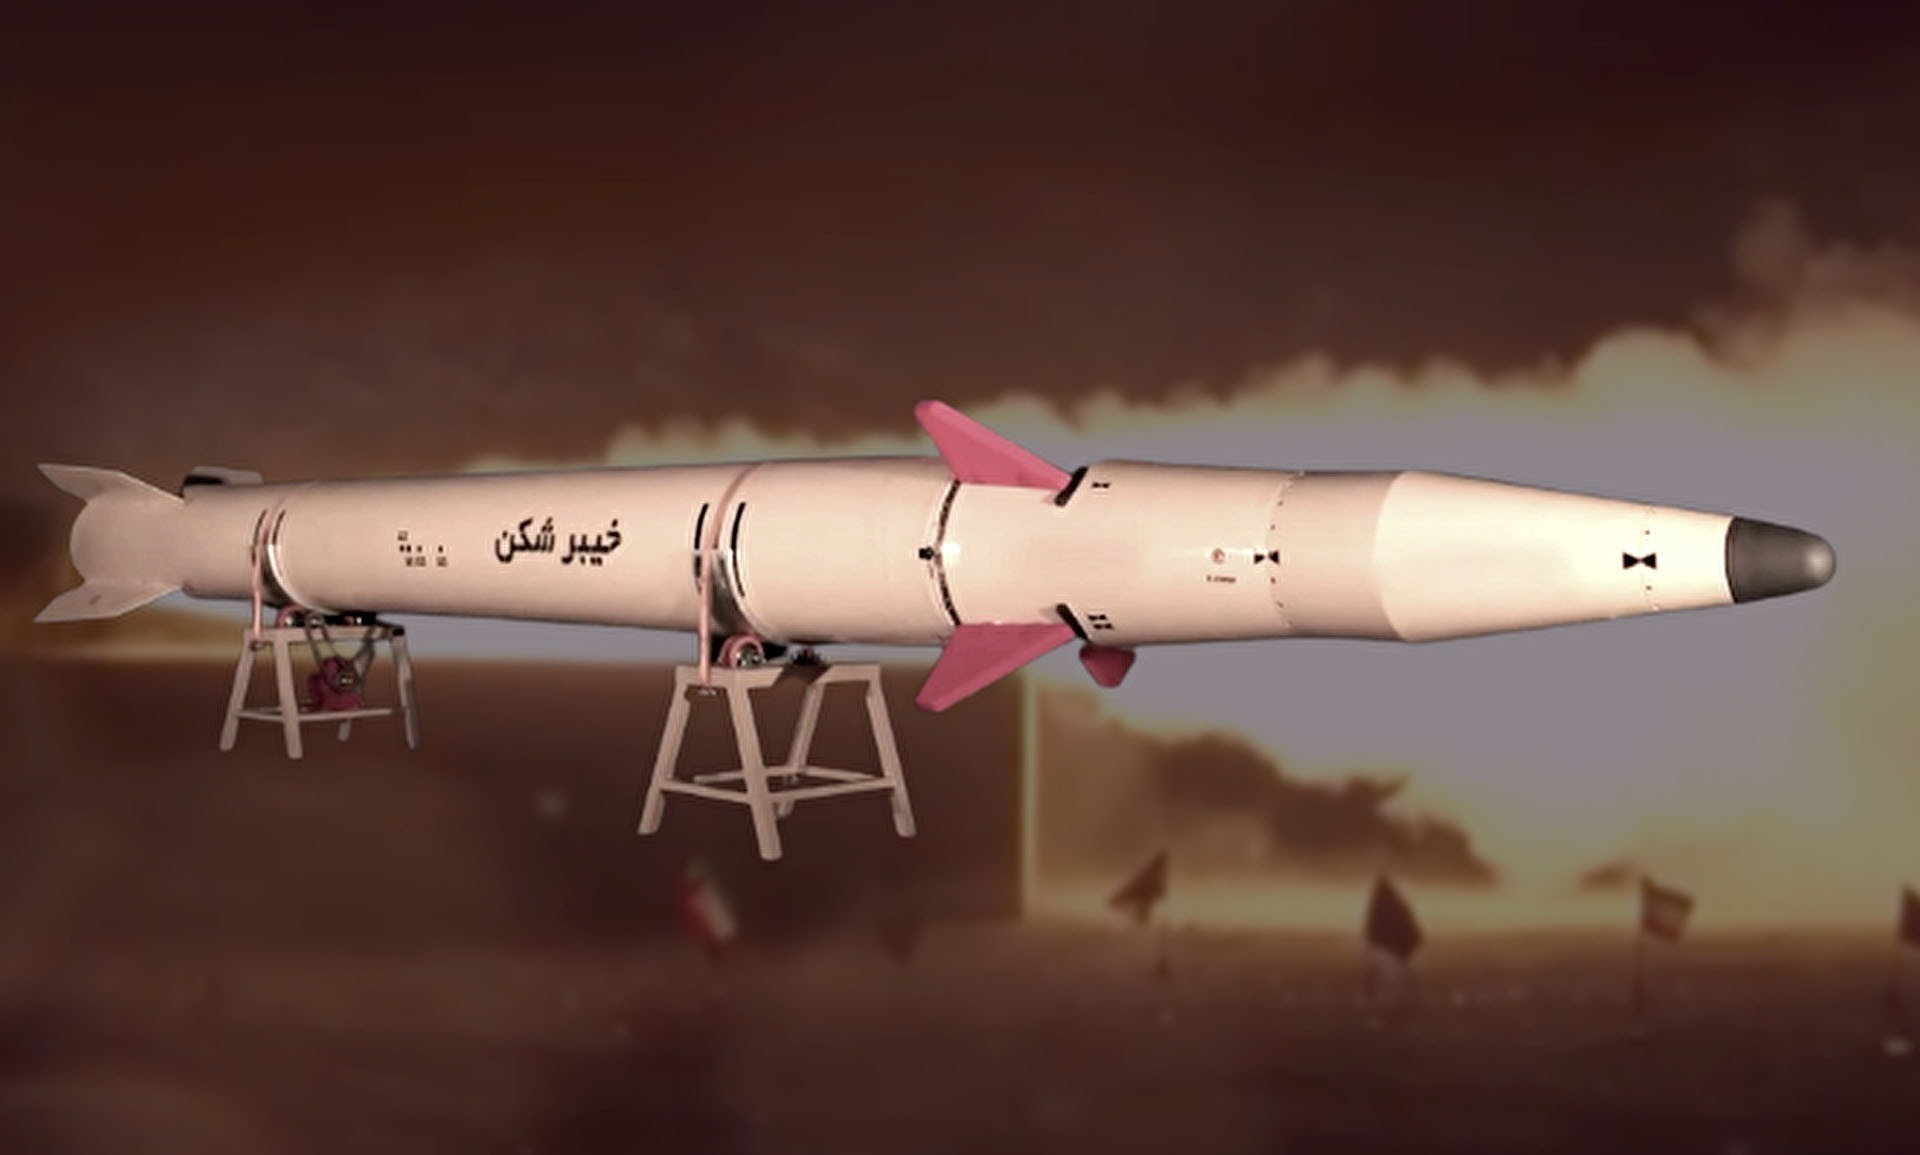
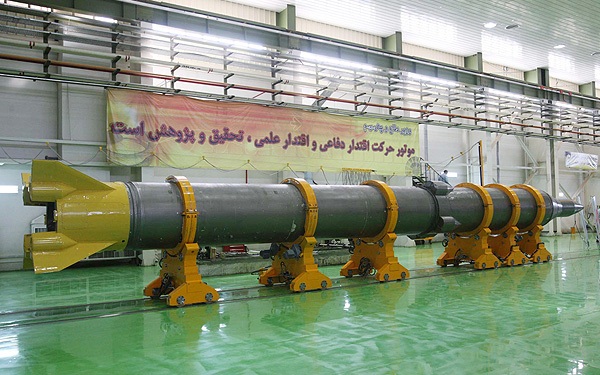
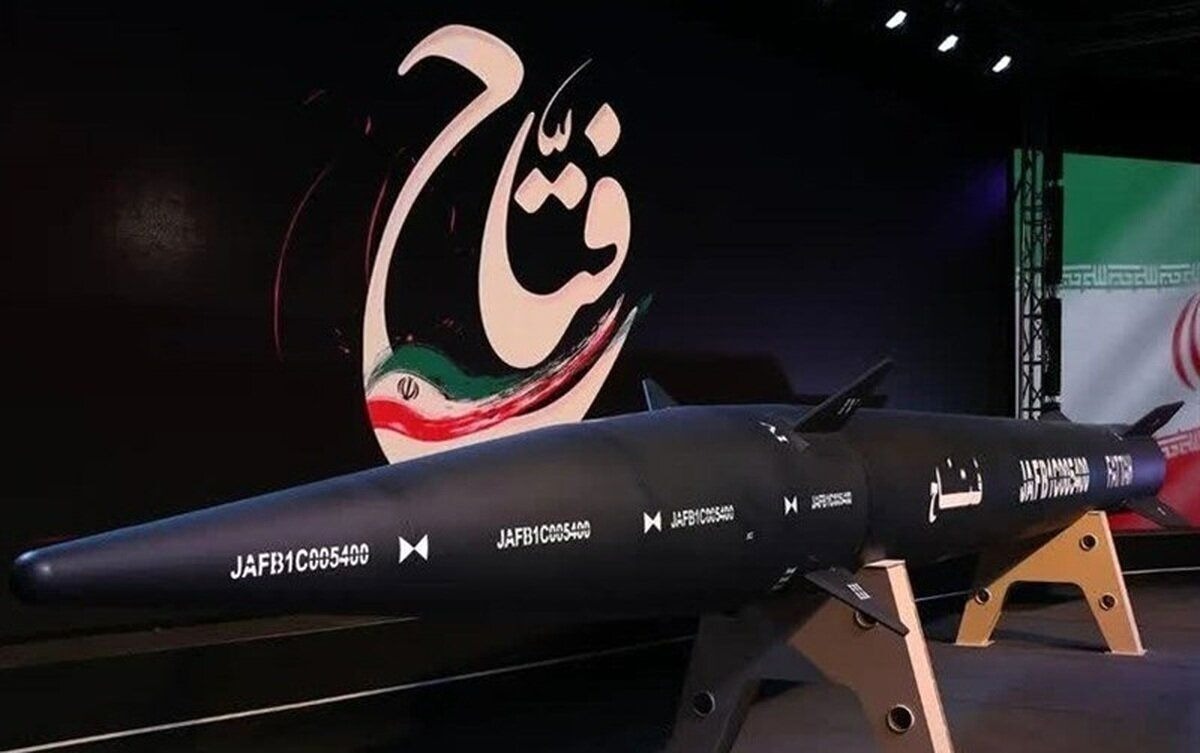
Which of B and C is more similar to A?
Raw Euclidean Distance
Khaybar vs. Sejjil (B): km and Mach, so .
Khaybar vs. Fatāh (C): km and Mach, so .
Fatāh looks ten times closer. The reason is arithmetic rather than similarity: the range column takes values in the thousands, so 50 km is a small number next to 5 or 9 in the speed column. The feature with the larger numerical range decides the answer.
Standardized Distance
Divide each feature by its standard deviation, , so that both are measured in standard deviations. For the three missiles
range: km, population km (sample km);
speed: Mach, population Mach (sample Mach).
StandardScaler divides by the population standard deviation, by and not by ,
which is why the distances below use 271.8 and 3.68 while pandas prints 332.9 and 4.51. In
z-units A is , B is and C is , so
Khaybar vs. Sejjil: ;
Khaybar vs. Fatāh: .
| Comparison | Raw distance | Standardized distance |
|---|---|---|
| Khaybar vs. Sejjil | 550.02 | 2.44 |
| Khaybar vs. Fatāh | 50.80 | 2.45 |
The answer flips, by a hair: after standardization Sejjil is the nearer neighbour.
Which Answer Is Right?
Neither. Standardizing says the two features deserve equal weight; the raw distance says one kilometre counts as much as one Mach. Both are assumptions about the problem, not facts about missiles, and the example is built so that they disagree. That is the lesson to keep: for any method based on Euclidean distance — k-NN, k-means, the input layer of a network — the scaling is part of the model, and it should be chosen rather than inherited from the units in which the data happen to be stored.
The Code
The next cell does the arithmetic: raw distances, then StandardScaler, then the same
Euclidean distance on the standardized columns.
Source
import numpy as np
import pandas as pd
from sklearn.preprocessing import StandardScaler

# ============================================
# 1. REALISTIC IRANIAN MISSILE DATASET
# ============================================
data = {
    'Name': ['Khaybar Shikan', 'Sejjil', 'Fatāh'],
    'Range_km': [1450, 2000, 1400],
    'Speed_Mach': [5, 10, 14]
}

df = pd.DataFrame(data)
df.set_index('Name', inplace=True)

# Target: Compare Khaybar Shikan to Sejjil and Fatāh
target_name = 'Khaybar Shikan'
target = df.loc[target_name].values
other_names = ['Sejjil', 'Fatāh']
others = df.loc[other_names].values

# ============================================
# 2. RAW EUCLIDEAN DISTANCE (Unscaled)
# ============================================
raw_dist = np.linalg.norm(others - target, axis=1)

print("=== RAW EUCLIDEAN DISTANCE (Unscaled) ===")
for name, dist in zip(other_names, raw_dist):
    print(f"Distance to {name}: {dist:.2f}")

# ============================================
# 3. SCALED EUCLIDEAN DISTANCE (Standardized)
# ============================================
scaler = StandardScaler()
scaled_data = scaler.fit_transform(df[['Range_km', 'Speed_Mach']])
df_scaled = pd.DataFrame(scaled_data, index=df.index, columns=df.columns)

target_scaled = df_scaled.loc[target_name].values
others_scaled = df_scaled.loc[other_names].values

scaled_dist = np.linalg.norm(others_scaled - target_scaled, axis=1)

print("\n=== SCALED EUCLIDEAN DISTANCE (Normalized) ===")
for name, dist in zip(other_names, scaled_dist):
    print(f"Distance to {name}: {dist:.2f}")

# ============================================
# 4. SHOW THE FLIP
# ============================================
raw_winner = other_names[np.argmin(raw_dist)]
scaled_winner = other_names[np.argmin(scaled_dist)]

print("\n--- ANALYSIS ---")
print(f"Winner with raw distances: {raw_winner}")
print(f"Winner after standardization: {scaled_winner}")

# ============================================
# 5. SHOW STATISTICS
# ============================================
print("\n--- DATASET STATISTICS ---")
print(f"Range Std Dev: {df['Range_km'].std():.2f} km")
print(f"Speed Std Dev: {df['Speed_Mach'].std():.2f} Mach")
=== RAW EUCLIDEAN DISTANCE (Unscaled) ===
Distance to Sejjil: 550.02
Distance to Fatāh: 50.80

=== SCALED EUCLIDEAN DISTANCE (Normalized) ===
Distance to Sejjil: 2.44
Distance to Fatāh: 2.45

--- ANALYSIS ---
Winner with raw distances: Fatāh
Winner after standardization: Sejjil

--- DATASET STATISTICS ---
Range Std Dev: 332.92 km
Speed Std Dev: 4.51 Mach
The two printed statistics use different denominators: df.std() is the sample standard
deviation () while StandardScaler uses the population one (). Both are reasonable;
the distances above come from the population version.
3. The Covariance Matrix
The covariance matrix is a square matrix that summarizes the variances and covariances of a set of random variables. For a dataset with features, the covariance matrix is a matrix defined as:
Where:
: The variance of the -th feature (diagonal elements).
: The covariance between the -th and -th features (off-diagonal elements).
Properties:
Symmetric: , so .
Positive Semi-Definite: All eigenvalues are non-negative ().
4. Geometric Interpretation of the Covariance Matrix
The covariance matrix defines the shape and orientation of the data distribution in the feature space.
Eigenvectors (Directions): The eigenvectors of represent the principal axes of the data distribution. They indicate the directions of maximum variance.
Eigenvalues (Magnitudes): The corresponding eigenvalues represent the magnitude of variance along these eigenvector directions.
Ellipsoid: In 2D, the covariance matrix defines an ellipse. In -dimensions, it defines a hyper-ellipsoid. The axes of this ellipsoid are aligned with the eigenvectors, and the lengths of the axes are proportional to the square roots of the eigenvalues.
5. Linear Transformations and Covariance
To fully understand Mahalanobis distance and whitening, we must understand how covariance changes under linear transformations. The following theorem provides the mathematical foundation for transforming data to a “whitened” space.
Theorem 1 (Covariance Transformation Property)
Let be a random vector with mean and covariance matrix . Let be a constant transformation matrix. For a transformed random vector , the covariance matrix of is
Proof: We proceed by applying the definition of covariance and the linearity of expectation.
Mean of : First, observe that the mean of the centered vector is zero:
Covariance of :
Since , the covariance definition simplifies to .
By the linearity of the expectation operator, constant matrices and can be pulled out of the expectation:
Recognizing that the term inside the expectation is exactly the definition of :
Remark (Whitening Application): This property is fundamental to whitening. By choosing such that , we transform the data into a space where features are uncorrelated and have unit variance. Section 6 constructs this from the eigendecomposition of .
6. Whitening Transformation
Whitening is a preprocessing step that turns the covariance matrix into the identity. The transformed features are then uncorrelated and have unit variance.
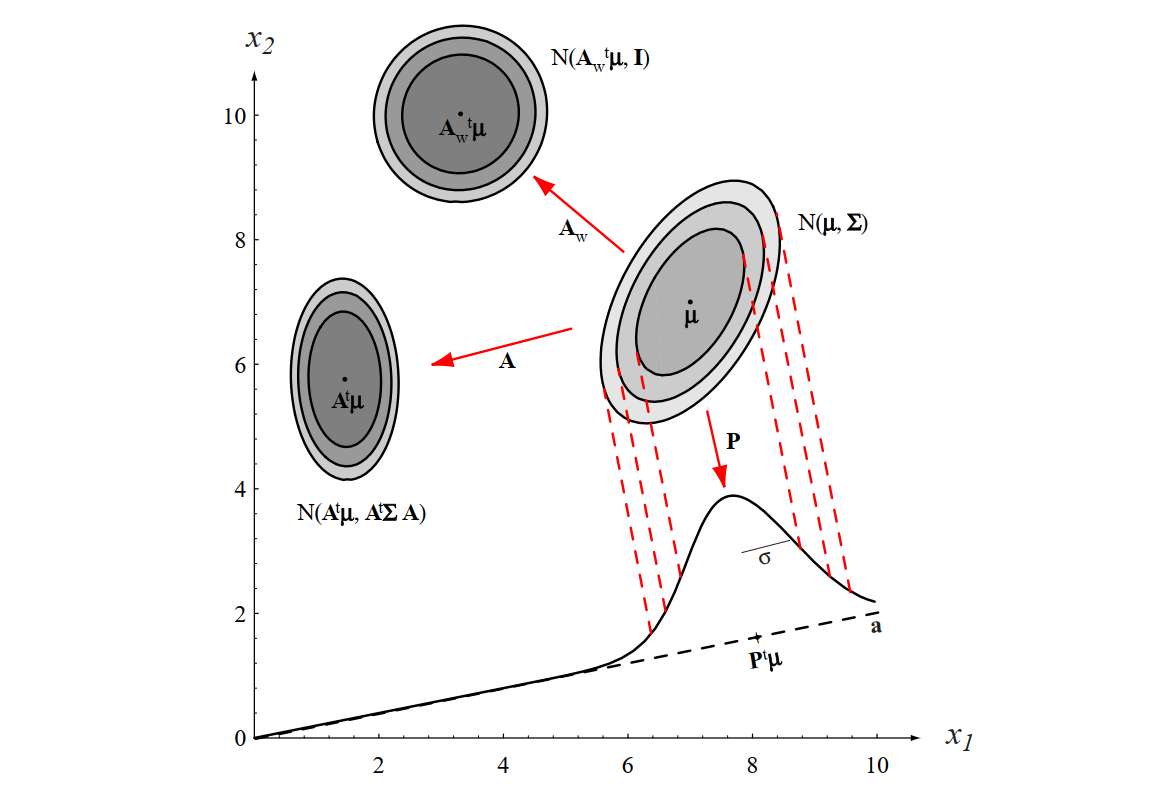
Figure 2.8 Duda et al. (2000): a linear transformation of the feature space maps an arbitrary normal distribution to another normal distribution.
We want a matrix such that has covariance . Section 5 gives , and the eigendecomposition of Section 4, , provides . Checking it:
Geometric Interpretation
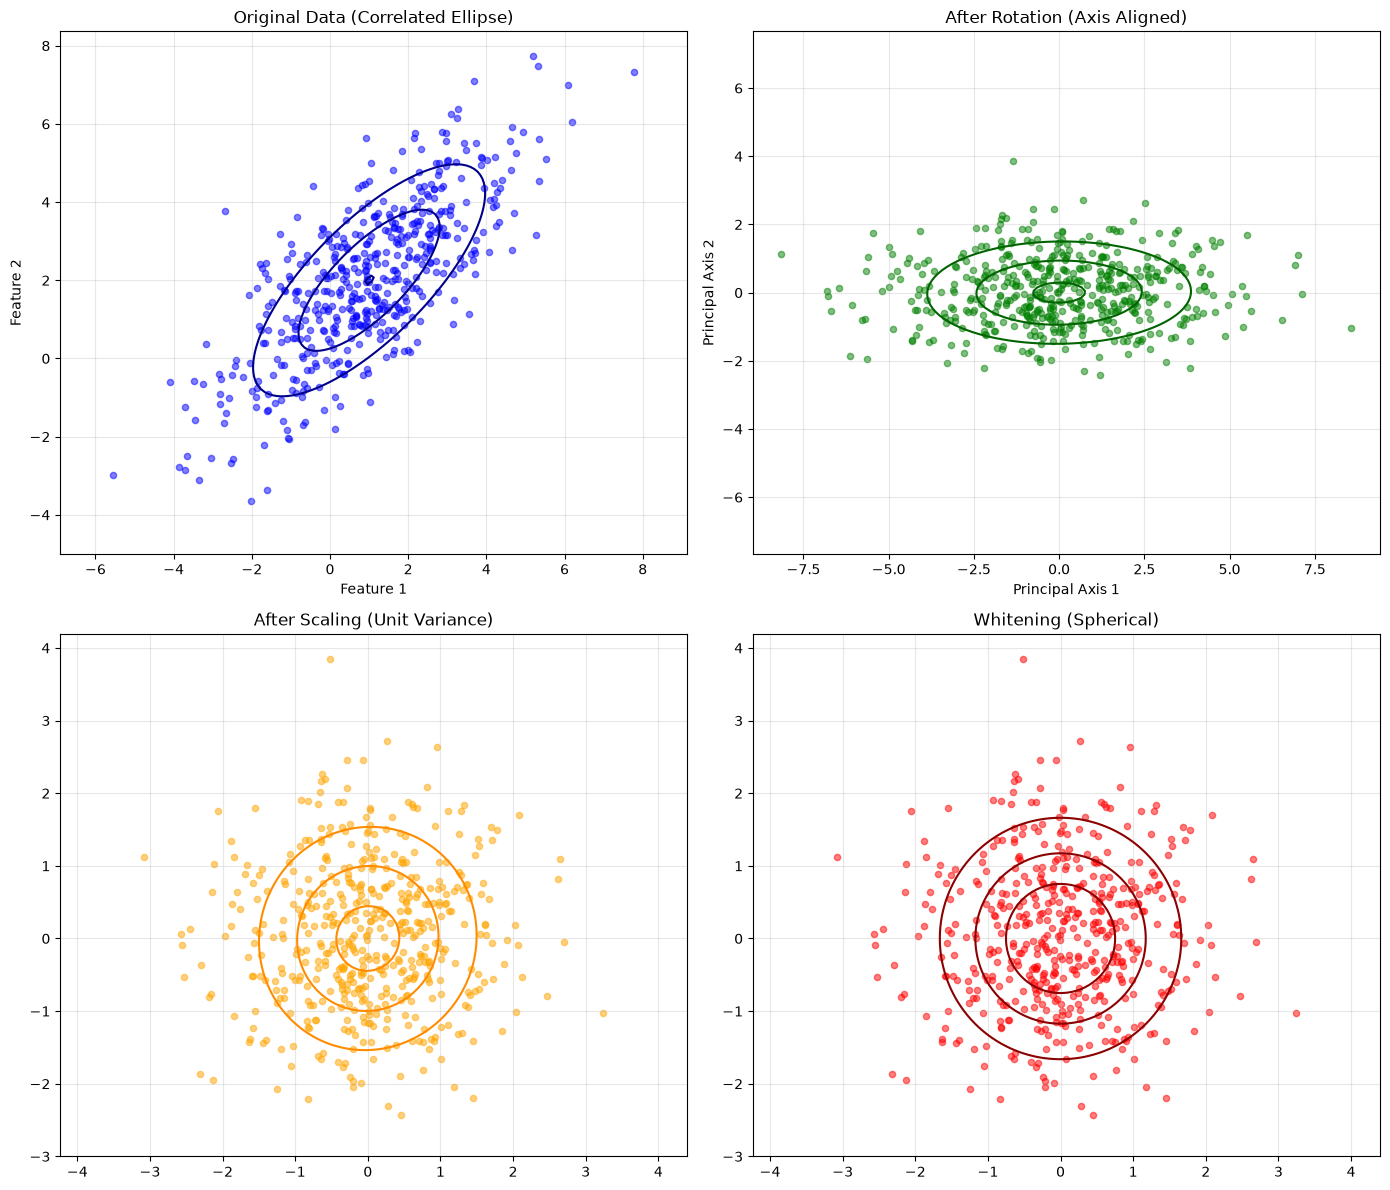
Rotation () aligns the data with the principal axes and removes the correlations.
Scaling () stretches or compresses each axis until its variance is 1.
The cloud becomes a sphere. In this space the Euclidean distance is the Mahalanobis distance of the original space — Section 7 proves the identity, and the code below shows it numerically.
The Same Two Points, Whitened
The code takes the correlated cloud and the two starred points of Section 1, applies , and plots the data before and after. On the left the two points are at the same Euclidean distance from the centre; on the right their Euclidean distances are their Mahalanobis distances in the original space.
Source
import numpy as np
import matplotlib.pyplot as plt
from scipy.spatial.distance import mahalanobis
from scipy.stats import multivariate_normal

# Generate 2D Gaussian random points
np.random.seed(42)
mean = [0, 0]
cov = [[1, 0.8], [0.8, 1]]  # Covariance matrix
points = np.random.multivariate_normal(mean, cov, 100)

# The center
center = mean

# Select two points with equal Euclidean distance to the center
point1 = np.array([1.5, 1.5])
point2 = np.array([-1.5, 1.5])

# Compute Euclidean distances
euclidean_dist1 = np.linalg.norm(point1 - center)
euclidean_dist2 = np.linalg.norm(point2 - center)

# Compute Mahalanobis distances
inv_cov = np.linalg.inv(cov)
mahalanobis_dist1 = mahalanobis(point1, center, inv_cov)
mahalanobis_dist2 = mahalanobis(point2, center, inv_cov)

# Whitening the data based on Duda's book
# Step 1: Compute the eigenvalues and eigenvectors of the covariance matrix
eigenvals, eigenvecs = np.linalg.eigh(cov)
idx = np.argsort(eigenvals)[::-1]
eigenvals = eigenvals[idx]
eigenvecs = eigenvecs[:, idx]

# Step 2: Construct the whitening matrix
D = np.diag(1.0 / np.sqrt(eigenvals))  # Diagonal matrix of inverse square roots of eigenvalues
W = np.dot(eigenvecs, D)  # Whitening matrix

# Step 3: Whiten the data
whitened_points = np.dot(points - center, W)  # Subtract mean and apply whitening transformation
whitened_point1 = np.dot(point1 - center, W)
whitened_point2 = np.dot(point2 - center, W)

# Compute Euclidean distances in the whitened space
whitened_euclidean_dist1 = np.linalg.norm(whitened_point1)
whitened_euclidean_dist2 = np.linalg.norm(whitened_point2)

# Plot the original and whitened data
plt.figure(figsize=(12, 6))

# Plot original data
plt.subplot(1, 2, 1)
plt.scatter(points[:, 0], points[:, 1], alpha=0.5, label='Random Points')
plt.scatter(center[0], center[1], color='red', label='Center')
plt.scatter(point1[0], point1[1], color='green', marker='*', s=150, label=f'Point 1 (Euclidean: {euclidean_dist1:.2f}, Mahalanobis: {mahalanobis_dist1:.2f})')
plt.scatter(point2[0], point2[1], color='blue', marker='*', s=150, label=f'Point 2 (Euclidean: {euclidean_dist2:.2f}, Mahalanobis: {mahalanobis_dist2:.2f})')

# Create a grid of points for the original data
x, y = np.mgrid[-3:3:.01, -3:3:.01]
pos = np.dstack((x, y))

# Compute the Gaussian distribution on the grid
rv = multivariate_normal(mean, cov)
plt.contour(x, y, rv.pdf(pos), levels=3, cmap='viridis')

plt.legend()
plt.title('Original Data')
plt.xlabel('Feature 1')
plt.ylabel('Feature 2')
plt.axis('equal')

# Plot whitened data
plt.subplot(1, 2, 2)
plt.scatter(whitened_points[:, 0], whitened_points[:, 1], alpha=0.5, label='Whitened Points')
plt.scatter(0, 0, color='red', label='Center')
plt.scatter(whitened_point1[0], whitened_point1[1], color='green', marker='*', s=150, label=f'Point 1 (Euclidean: {whitened_euclidean_dist1:.2f})')
plt.scatter(whitened_point2[0], whitened_point2[1], color='blue', marker='*', s=150, label=f'Point 2 (Euclidean: {whitened_euclidean_dist2:.2f})')

# Create a grid of points for the whitened data
x_whitened, y_whitened = np.mgrid[-3:3:.01, -3:3:.01]
pos_whitened = np.dstack((x_whitened, y_whitened))

# Compute the Gaussian distribution on the grid for whitened data
rv_whitened = multivariate_normal([0, 0], np.eye(2))  # Covariance matrix is identity after whitening
plt.contour(x_whitened, y_whitened, rv_whitened.pdf(pos_whitened), levels=3, cmap='viridis')

plt.legend()
plt.title('Whitened Data')
plt.xlabel('Whitened Feature 1')
plt.ylabel('Whitened Feature 2')
plt.axis('equal')

plt.tight_layout()
plt.show()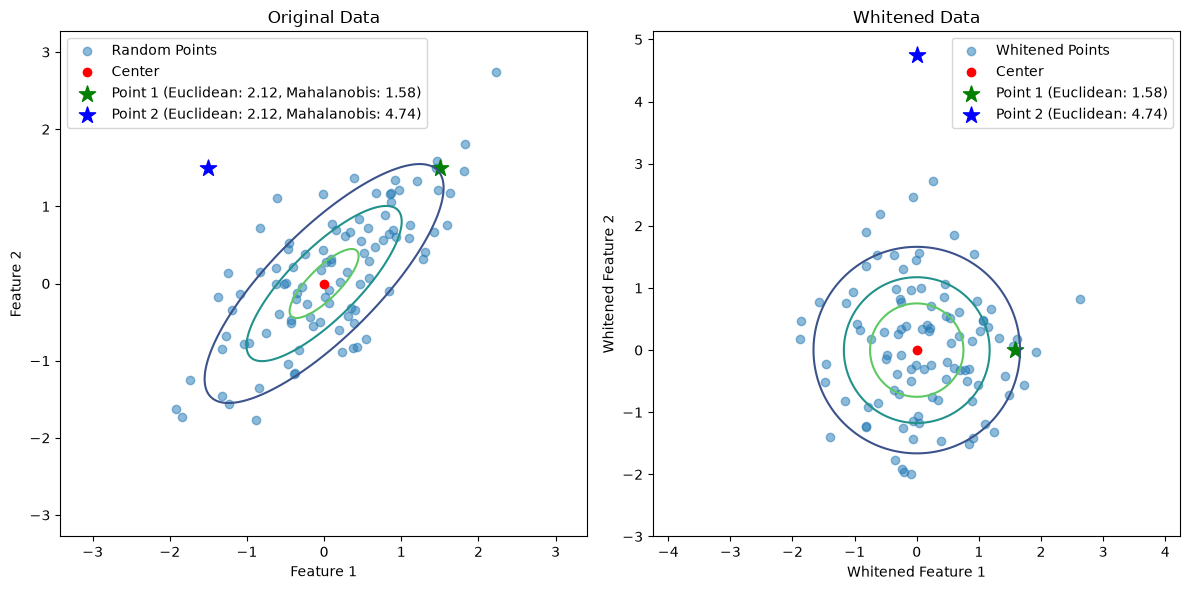
Both points are 2.12 from the centre in the original Euclidean sense. Their Mahalanobis distances are 1.58 for the point along the principal axis and 4.74 for the point across it; after whitening the Euclidean distances are exactly those two numbers, in the same order. The circle of constant radius in the right panel is an ellipse of constant Mahalanobis distance in the left one.
7. The Mahalanobis Distance
In Section 6 we fixed the transformation and asked which covariance it produces. Here we ask the inverse question: which norm on the transformed coordinates reproduces the Mahalanobis distance of the original space?
The Mahalanobis distance is a measure of the distance between a point and a distribution with mean and covariance matrix . It is defined as:
This distance is central to many multivariate statistical methods, including Bayesian decision theory for classification, because it accounts for the underlying structure (variances and correlations) of the data.
The Key Insight
The covariance transformation formula from Section 5 is the fundamental mathematical foundation for both whitening transformation and Mahalanobis distance.
Recall the Mahalanobis distance:
Now consider the whitened space: If we define where makes , then:
For this to equal the Mahalanobis distance, we need to show that .
Proof:
We are given: and
We aim to show that
Step 1: Compute
Substitute :
Now, transpose the second factor:
Since is a diagonal matrix with positive eigenvalues (implying invertibility), is also diagonal and symmetric, so:
Thus,
Step 2: Compute using the inverse of a diagonalized matrix
We are given:
Since is an orthogonal matrix (i.e., ), we know that:
Because is orthogonal:
So
Therefore,
We have shown that:
Key insight: The orthogonality of allows us to simplify the inverse of elegantly, which is essential for establishing the result.
Key Relationship
| Concept | Mathematical Expression | Purpose |
|---|---|---|
| Covariance Transformation | Describes how covariance changes under linear transformation | |
| Whitening Matrix | Transforms data to unit covariance | |
| Mahalanobis Distance | Distance accounting for covariance structure | |
| Euclidean Distance (Whitened) | Distance after covariance normalization | |
| Key Equivalence | Mahalanobis = Euclidean in whitened space |
8. Python Implementation, Step by Step
import numpy as np
import matplotlib.pyplot as plt
from scipy.stats import multivariate_normal

np.random.seed(42)

# ============================================================================
# 1. GENERATE CORRELATED DATA
# ============================================================================
print("=" * 70)
print("STEP 1: Generate Correlated Data (Original Space)")
print("=" * 70)

mean = np.array([1, 2])
cov_original = np.array([[4, 3], [3, 4]])  # Correlated data
n_samples = 500
data_original = np.random.multivariate_normal(mean, cov_original, n_samples)

print(f"Original Covariance:\n{cov_original}")

# ============================================================================
# 2. EIGEN DECOMPOSITION
# ============================================================================
print("\n" + "=" * 70)
print("STEP 2: Eigen Decomposition (Rotation + Scaling Factors)")
print("=" * 70)

eigenvalues, eigenvectors = np.linalg.eigh(cov_original)
idx = np.argsort(eigenvalues)[::-1]
eigenvalues = eigenvalues[idx]
eigenvectors = eigenvectors[:, idx]
print(f"\nEigenvalues (λ): {eigenvalues}")
print(f"\nEigenvectors (Φ):")
print(eigenvectors)
======================================================================
STEP 1: Generate Correlated Data (Original Space)
======================================================================
Original Covariance:
[[4 3]
 [3 4]]

======================================================================
STEP 2: Eigen Decomposition (Rotation + Scaling Factors)
======================================================================

Eigenvalues (λ): [7. 1.]

Eigenvectors (Φ):
[[ 0.70710678 -0.70710678]
 [ 0.70710678  0.70710678]]
# ============================================================================
# 3. ROTATION ONLY (Phi^T: removes the correlation)
# ============================================================================
print("\n" + "=" * 70)
print("STEP 3: Rotation Only")
print("=" * 70)

data_rotated = (data_original - mean) @ eigenvectors
cov_rotated = np.cov(data_rotated.T)

print(f"\nCovariance after Rotation (diagonal, up to sampling error):")
print(cov_rotated)
print(f"Off-diagonal before rotation: {cov_original[0, 1]:.4f}")
print(f"Off-diagonal after rotation: {cov_rotated[0, 1]:.4f}")

# ============================================================================
# 4. SCALING AFTER ROTATION (divide each axis by sqrt(lambda))
# ============================================================================
print("\n" + "=" * 70)
print("STEP 4: Scaling Only (Λ^(-1/2) normalizes variance)")
print("=" * 70)

scale_factors = 1.0 / np.sqrt(eigenvalues)
data_scaled = data_rotated @ np.diag(scale_factors)
cov_scaled = np.cov(data_scaled.T)

print(f"\nCovariance after Scaling (identity, up to sampling error):")
print(cov_scaled)
======================================================================
STEP 3: Rotation Only
======================================================================

Covariance after Rotation (diagonal, up to sampling error):
[[6.54609064 0.06692453]
 [0.06692453 0.98399756]]
Off-diagonal before rotation: 3.0000
Off-diagonal after rotation: 0.0669

======================================================================
STEP 4: Scaling Only (Λ^(-1/2) normalizes variance)
======================================================================

Covariance after Scaling (identity, up to sampling error):
[[0.93515581 0.02529509]
 [0.02529509 0.98399756]]
# ============================================================================
# 5. WHITENING: the same two steps as one matrix, W = Phi Lambda^(-1/2)
# ============================================================================
print("\n" + "=" * 70)
print("STEP 5:  Whitening (W = ΦΛ^(-1/2))")
print("=" * 70)

W = eigenvectors @ np.diag(scale_factors)
data_whitened = W.T @ (data_original - mean).T
data_whitened = data_whitened.T

print(f"\nWhitening Matrix (W = ΦΛ^(-1/2)):")
print(W)
print(f"\nCovariance after Whitening (W^T Σ W):")
print(np.cov(data_whitened.T))
======================================================================
STEP 5:  Whitening (W = ΦΛ^(-1/2))
======================================================================

Whitening Matrix (W = ΦΛ^(-1/2)):
[[ 0.26726124 -0.70710678]
 [ 0.26726124  0.70710678]]

Covariance after Whitening (W^T Σ W):
[[0.93515581 0.02529509]
 [0.02529509 0.98399756]]
The printed covariances are those of a sample of 500 points, not of the true
, and np.cov divides by
. That is why the diagonal after rotation reads 6.55 and 0.98 instead of exactly 7 and 1,
and why after whitening it reads 0.94 and 0.98 instead of exactly 1: the transformation is
exact, the estimate of the covariance is not. Raise n_samples and the entries converge to the
identity.
# ============================================================================
# 6. VISUALIZATION
# ============================================================================
print("\n" + "=" * 70)
print("STEP 6: Visualization of Transformation")
print("=" * 70)

fig, axes = plt.subplots(2, 2, figsize=(14, 12))

# Original Data
axes[0, 0].scatter(data_original[:, 0], data_original[:, 1], alpha=0.5, s=20, color='blue', label='Original')
pos = np.dstack(np.mgrid[-5:5:100j, -5:5:100j])
axes[0, 0].contour(pos[:,:,0], pos[:,:,1], multivariate_normal(mean, cov_original).pdf(pos), levels=3, colors='darkblue')
axes[0, 0].set_title('Original Data (Correlated Ellipse)')
axes[0, 0].set_xlabel('Feature 1'); axes[0, 0].set_ylabel('Feature 2')
axes[0, 0].grid(True, alpha=0.3); axes[0, 0].axis('equal')

# After Rotation
axes[0, 1].scatter(data_rotated[:, 0], data_rotated[:, 1], alpha=0.5, s=20, color='green', label='Rotated')
pos = np.dstack(np.mgrid[-5:5:100j, -5:5:100j])
axes[0, 1].contour(pos[:,:,0], pos[:,:,1], multivariate_normal(np.zeros(2), cov_rotated).pdf(pos), levels=3, colors='darkgreen')
axes[0, 1].set_title('After Rotation (Axis Aligned)')
axes[0, 1].set_xlabel('Principal Axis 1'); axes[0, 1].set_ylabel('Principal Axis 2')
axes[0, 1].grid(True, alpha=0.3); axes[0, 1].axis('equal')

# After Scaling
axes[1, 0].scatter(data_scaled[:, 0], data_scaled[:, 1], alpha=0.5, s=20, color='orange', label='Scaled')
pos = np.dstack(np.mgrid[-3:3:100j, -3:3:100j])
axes[1, 0].contour(pos[:,:,0], pos[:,:,1], multivariate_normal(np.zeros(2), cov_scaled).pdf(pos), levels=3, colors='darkorange')
axes[1, 0].set_title('After Scaling (Unit Variance)')
axes[1, 0].grid(True, alpha=0.3); axes[1, 0].axis('equal')

# Combined Whitening
axes[1, 1].scatter(data_whitened[:, 0], data_whitened[:, 1], alpha=0.5, s=20, color='red', label='Whitened')
pos = np.dstack(np.mgrid[-3:3:100j, -3:3:100j])
axes[1, 1].contour(pos[:,:,0], pos[:,:,1], multivariate_normal(np.zeros(2), np.eye(2)).pdf(pos), levels=3, colors='darkred')
axes[1, 1].set_title('Whitening (Spherical)')
axes[1, 1].grid(True, alpha=0.3); axes[1, 1].axis('equal')

plt.tight_layout()
plt.show()
======================================================================
STEP 6: Visualization of Transformation
======================================================================
# ============================================================================
# 7. MAHALANOBIS DISTANCE VERIFICATION
# ============================================================================
print("\n" + "=" * 70)
print("STEP 7: Mahalanobis Distance = Euclidean in Whitened Space")
print("=" * 70)

test_point = np.array([4, 4])
inv_cov = np.linalg.inv(cov_original)
mahalanobis_dist = np.sqrt((test_point - mean) @ inv_cov @ (test_point - mean))
test_point_whitened = W.T @ (test_point - mean)
euclidean_dist_whitened = np.linalg.norm(test_point_whitened)

print(f"\nTest Point: {test_point}")
print(f"Mahalanobis Distance (Original Space): {mahalanobis_dist:.4f}")
print(f"Euclidean Distance (Whitened Space): {euclidean_dist_whitened:.4f}")
print("\nMahalanobis distance and whitened Euclidean distance agree.")
======================================================================
STEP 7: Mahalanobis Distance = Euclidean in Whitened Space
======================================================================

Test Point: [4 4]
Mahalanobis Distance (Original Space): 1.5119
Euclidean Distance (Whitened Space): 1.5119

Mahalanobis distance and whitened Euclidean distance agree.
9. The Covariance Matrix in Bayesian Decision Theory
The Gaussian class-conditional density of the Bayesian decision theory page is
where and are estimated per class by maximum likelihood (MLE page).
The exponent is exactly half the squared Mahalanobis distance from to .
A common covariance, for all , makes the log-discriminant linear, and the boundaries are hyperplanes: that is LDA.
A separate covariance per class leaves a quadratic term and gives QDA.
If is singular — too few samples per class compared with — the density, and with it the Mahalanobis distance, is undefined until the estimate is regularised.
So the Mahalanobis distance is not a distance formula added to classification: it is the geometry of the Gaussian classifier.
10. Mahalanobis Distance and Its Role
For one feature, the z-score measures how many standard deviations a value is from the mean. The Mahalanobis distance is the same idea for features:
The role of is taken by the covariance matrix, so does two things at once: it scales each feature by its variance and it rotates the space to remove the correlations. Geometrically, counts how many “standard deviations” a point is from the centre of an ellipsoidal cloud, measuring the distance along the stretched and rotated axes of that ellipsoid.
From a Distance to a Test
For data drawn from the squared Mahalanobis distance is a variable with degrees of freedom, . The distance therefore converts into a probability statement, which is what an anomaly detector needs: the 95% and 99% quantiles of are 5.99 and 9.21, so a point with beyond them lies outside the corresponding probability contour of the ellipse. This is the multivariate version of the “more than two standard deviations away” rule, and it is the most common practical use of the distance.
11. Standardization, PCA and Whitening
All three transformations start from the same statistics and are easy to confuse. In terms of the eigendecomposition :
Standardization divides each feature by its own standard deviation. It changes the diagonal of the covariance to one but leaves the off-diagonal correlations in place.
PCA rotates to the principal axes, , and has covariance : the correlations are gone, the variances remain.
Whitening rotates and then scales, , and has covariance .
| Property | Standardization | PCA | Whitening |
|---|---|---|---|
| Goal | comparable units | reduce dimension, keep variance | unit variance and no correlation |
| Transformation | |||
| Covariance afterwards | correlations kept | diagonal, | identity, |
| Shape of the cloud | same ellipse | axis-aligned ellipse | sphere |
| Euclidean Mahalanobis? | no | no | yes |
| Loss of information | none | if components are kept | none at full rank |
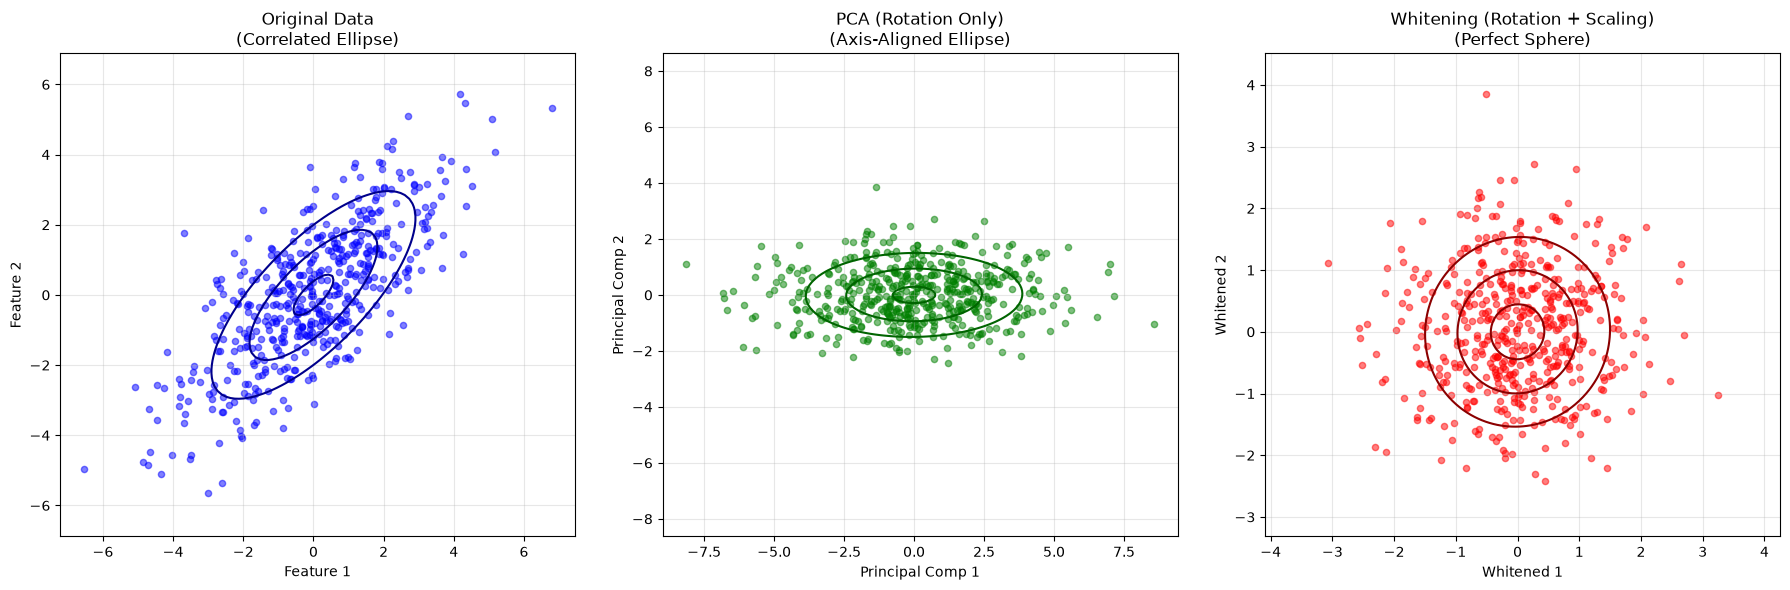
The one that makes Euclidean distance meaningful is whitening: after standardization the features still have different variances along the correlated directions, and after PCA the axes still have the variances . Only when every direction has variance 1 does a Euclidean ball become a contour of constant probability density.
Demonstration: PCA versus Whitening
The next cell applies both transformations to the same cloud and prints the three distances of one test point.
Source
import numpy as np
import matplotlib.pyplot as plt
from scipy.stats import multivariate_normal

np.random.seed(42)

# ============================================================================
# 1. GENERATE CORRELATED DATA
# ============================================================================
mean = np.array([0, 0])
cov_original = np.array([[4, 3], [3, 4]])  # Correlated data
n_samples = 500
data_original = np.random.multivariate_normal(mean, cov_original, n_samples)
# print(f"Original data shape: {data_original.shape}")  # (500, 2)

# ============================================================================
# 2. PREPARE TRANSFORMATIONS
# ============================================================================
eigenvalues, eigenvectors = np.linalg.eigh(cov_original)
idx = np.argsort(eigenvalues)[::-1]
eigenvalues = eigenvalues[idx]
eigenvectors = eigenvectors[:, idx]

# PCA Transformation (Rotation Only)
# Correct: Keep shape (n_samples, n_features)
data_pca = (data_original - mean) @ eigenvectors

# Whitening Transformation (Rotation + Scaling)
scale_factors = 1.0 / np.sqrt(eigenvalues)
data_whitened = data_pca @ np.diag(scale_factors)

# print(f"PCA data shape: {data_pca.shape}")  # (500, 2)
# print(f"Whitened data shape: {data_whitened.shape}")  # (500, 2)

# ============================================================================
# 3. COMPUTE COVARIANCES
# ============================================================================
cov_original_computed = np.cov(data_original, rowvar=False)
cov_pca = np.cov(data_pca, rowvar=False)
cov_white = np.cov(data_whitened, rowvar=False)

# print(f"\nCovariance shapes:")
# print(f"Original: {cov_original_computed.shape}")  # (2, 2)
# print(f"PCA: {cov_pca.shape}")  # (2, 2)
# print(f"Whitened: {cov_white.shape}")  # (2, 2)

# ============================================================================
# 4. VISUALIZATION
# ============================================================================
print("\n" + "=" * 70)
print("COMPARISON: Original → PCA → Whitening")
print("=" * 70)

fig, axes = plt.subplots(1, 3, figsize=(18, 6))

# --- Plot 1: Original ---
axes[0].scatter(data_original[:, 0], data_original[:, 1], alpha=0.5, s=20, color='blue')
x, y = np.mgrid[-6:6:100j, -6:6:100j]
pos = np.dstack((x, y))
axes[0].contour(x, y, multivariate_normal(mean, cov_original_computed).pdf(pos), levels=3, colors='darkblue')
axes[0].set_title('Original Data\n(Correlated Ellipse)')
axes[0].set_xlabel('Feature 1'); axes[0].set_ylabel('Feature 2')
axes[0].grid(True, alpha=0.3); axes[0].axis('equal')

# --- Plot 2: PCA (Rotation Only) ---
axes[1].scatter(data_pca[:, 0], data_pca[:, 1], alpha=0.5, s=20, color='green')
x, y = np.mgrid[-5:5:100j, -5:5:100j]
pos = np.dstack((x, y))
axes[1].contour(x, y, multivariate_normal(np.zeros(2), cov_pca).pdf(pos), levels=3, colors='darkgreen')
axes[1].set_title('PCA (Rotation Only)\n(Axis-Aligned Ellipse)')
axes[1].set_xlabel('Principal Comp 1'); axes[1].set_ylabel('Principal Comp 2')
axes[1].grid(True, alpha=0.3); axes[1].axis('equal')

# --- Plot 3: Whitening (Rotation + Scaling) ---
axes[2].scatter(data_whitened[:, 0], data_whitened[:, 1], alpha=0.5, s=20, color='red')
x, y = np.mgrid[-3:3:100j, -3:3:100j]
pos = np.dstack((x, y))
axes[2].contour(x, y, multivariate_normal(np.zeros(2), cov_white).pdf(pos), levels=3, colors='darkred')
axes[2].set_title('Whitening (Rotation + Scaling)\n(Perfect Sphere)')
axes[2].set_xlabel('Whitened 1'); axes[2].set_ylabel('Whitened 2')
axes[2].grid(True, alpha=0.3); axes[2].axis('equal')

plt.tight_layout()
plt.show()

# ============================================================================
# 5. DISTANCE COMPARISON
# ============================================================================
print("\n" + "=" * 70)
print("Distance Metrics for a Test Point")
print("=" * 70)

test_point = np.array([2.0, 1.0])
inv_cov = np.linalg.inv(cov_original)
mahal_dist = np.sqrt((test_point - mean) @ inv_cov @ (test_point - mean))

# Euclidean in PCA space
test_pca = (test_point - mean) @ eigenvectors
euclid_pca = np.linalg.norm(test_pca)

# Euclidean in Whitened space
test_white = test_pca @ np.diag(scale_factors)
euclid_white = np.linalg.norm(test_white)

print(f"\nTest Point: {test_point}")
print(f"Mahalanobis Distance (Original): {mahal_dist:.4f}")
print(f"Euclidean Distance (PCA Space):  {euclid_pca:.4f}")
print(f"Euclidean Distance (White Space): {euclid_white:.4f}")

print("\nConclusion: only whitening keeps the Euclidean distance equal to the Mahalanobis one.")
======================================================================
COMPARISON: Original → PCA → Whitening
======================================================================
======================================================================
Distance Metrics for a Test Point
======================================================================

Test Point: [2. 1.]
Mahalanobis Distance (Original): 1.0690
Euclidean Distance (PCA Space):  2.2361
Euclidean Distance (White Space): 1.0690

Conclusion: only whitening keeps the Euclidean distance equal to the Mahalanobis one.
Why This Matters for Mahalanobis Distance
PCA aligns the data with the principal axes but preserves the different variances along those axes. If you measure Euclidean distance in PCA space, a point 2 units away along a high-variance axis is treated the same as a point 2 units away along a low-variance axis. This distorts the statistical probability.
Whitening normalizes the variances. In this space, 1 unit equals 1 standard deviation in every direction. Therefore, Euclidean distance in whitened space correctly represents the statistical “surprise” (Mahalanobis distance) of a point.
Conclusion
The Mahalanobis distance is the natural generalization of the z-score to several dimensions. Through the covariance matrix it accounts for the scale of each feature and for the correlation between features, which Euclidean distance cannot do. It is used for
anomaly detection: flagging points that are statistically unlikely, against a quantile;
classification: it is the exponent of the Gaussian discriminant of Bayesian decision theory, whose parameters come from the MLE page;
preprocessing: whitening, after which Euclidean tools become valid.
Key Takeaways
Euclidean distance assumes spherical data; Mahalanobis distance assumes elliptical data.
The covariance matrix carries the shape, the scale and the orientation of the distribution.
Whitening maps to and turns the cloud into a sphere.
If then ; for this is .
In the whitened space Euclidean distance equals Mahalanobis distance; per-feature standardization does not achieve this, because it keeps the correlations.
References
Duda et al. (2000)
Duda, R. O., Hart, P. E., & Stork, D. G. (2000). Pattern Classification (2nd ed.). Wiley-Interscience, chapter 2.
- Duda, R. O., Hart, P. E., & Stork, D. G. (2000). Pattern Classification (2nd ed.). Wiley-Interscience.